We spent three weeks evaluating six business email finders last fall. Demos were smooth. Integrations all checked out. One vendor even threw in trial credits and a weekly check-in call. We picked the one with the cleanest UI and the largest contact database. Six weeks later, our bounce rate was sitting around 18%. SDRs started quietly verifying addresses by hand before sending anything. Nobody complained out loud—they just stopped trusting the tool.
That's when it hit me: the tool wasn't broken. Our evaluation was.
The question everyone asks (and why it's not the right one)
If you've ever sat through a business email finder evaluation, you know the drill. Does it integrate with HubSpot? How many contacts in the database? Is there a LinkedIn Sales Navigator integration? How fast can it enrich a list? And, increasingly, "is this an AI SDR or just a data tool?"
These are all reasonable questions. They're also the ones every vendor has already optimized their pitch around. Every demo will show you a clean, fast enrichment on a hand-picked list of Fortune 500 contacts. Nobody runs a demo on a messy 4,000-row CSV pulled from an old HubSpot export mixed with LinkedIn Sales Navigator scraped profiles and three years of conference badge data.
That's not dishonesty. It's just that demos are controlled environments. Your pipeline is not.
What's actually going on under the surface
The real variable in email verification accuracy isn't the tool. It's the intersection of the tool and your specific data. Same product, two different organizations, two completely different bounce rates.
Here's why that happens.
Verification is a spectrum, not a checkbox
Most vendors will tell you their email verification is "95% accurate" or better. What that number usually means: on a clean benchmark set of typical business emails, the tool correctly identifies valid vs invalid at that rate. Fair enough as a benchmark. But a benchmark set isn't your list.
Your list has catch-alls. Role-based addresses that route to a shared inbox. Personal domains where someone used their Gmail for work. Parked domains that look live but bounce on first send. Domain-only verifications that predict "likely valid" but can't actually confirm the mailbox exists. Those categories are where accuracy falls apart, and where the benchmark stops being useful.
When someone asks me what to look for in a business email finder, I've started answering with a different question: what does the vendor do when the answer is "I don't know"? Some mark it uncertain. Some mark it valid and let it bounce. That distinction matters more than the headline accuracy number.
The waterfall enrichment thing isn't marketing (mostly)
Waterfall enrichment—the approach where a tool queries multiple data sources in sequence, falling back to the next if the previous one misses—has become standard vocabulary in this category. It sounds like fluff. It isn't, exactly.
Single-source tools have coverage ceilings. Maybe 60–70% on a typical B2B list. Adding a second source can push that to 80%. Third and fourth sources start adding diminishing returns but also add "accept rate" mismatches—one source says valid, another says risky. The question becomes: which source wins, and does the tool tell you when they disagree?
I don't have hard data on how much waterfall enrichment actually improves net bounce rates across different industries, but based on what we've tracked internally over the past two quarters, the difference between a single-source tool and a well-ordered three-source waterfall has been meaningful. Roughly a third lower bounce percentage on the same input list. Take that with a grain of salt—it's one company's experience, not a benchmark.
Human review is not a quality feature. It's the workflow.
This is where I think most RevOps evaluations go sideways.
Tools that include a human review workflow—like the setup Okki Go uses, where an agent does the enrichment work but flags low-confidence records for human sign-off before they hit the outbound sequence—get evaluated as if the human step is a flaw. "Why would I want a human in the loop? The whole point is automation."
I used to think the same thing. Then I watched what our SDRs did when we removed the human step: they added it back manually. One at a time. They didn't trust the fully automated version, so they built their own review layer at about 20 hours a week of hidden labor.
Human-in-the-loop isn't slower automation. It's a different placement of the automation. The agent handles the 80% that's clean. The human handles the weird 20% that would otherwise poison the send. When we stopped pretending the human step was optional and started measuring it honestly, the math flipped.
What this actually costs
Poor email data doesn't fail loudly. It fails in a slow cascade.
Domain reputation first. Google's Postmaster Tools and Microsoft's SNDS both flag sustained bounce rates above roughly 5% as a reputation concern (verify current thresholds at postmaster.google.com). Once your sending domain shows reputation damage, every campaign suffers—cold outbound, transactional, even internal notifications. Fixing this takes weeks of consistent sending behavior. It's the kind of mess that makes a RevOps lead start asking uncomfortable questions about why the outbound volume dropped.
Then SDR trust. When reps don't believe the data, they stop using the tool. The $15K you spent on seats gets eaten by manual workarounds that show up nowhere in the reporting. I've watched this happen twice now, at two different companies. It always looks the same from the operations side: usage metrics drop, nobody tells you why, and the SDRs are quietly doing their own verification in a spreadsheet.
Then forecast reliability. If 15–20% of your outbound never reaches anyone, your reply rate math is off by the same amount. Intent data on top of a bad data layer isn't signal. It's noise with a confidence score attached.
I wish I'd tracked the actual weekly hours lost to manual verification more carefully. What I can say anecdotally is that it was enough to justify a full-time hire we never made—which is the kind of trade-off that looks fine on a budget line and shows up as burnout six months later.
What I'd actually evaluate next time
A few things I'd weight higher than I used to.
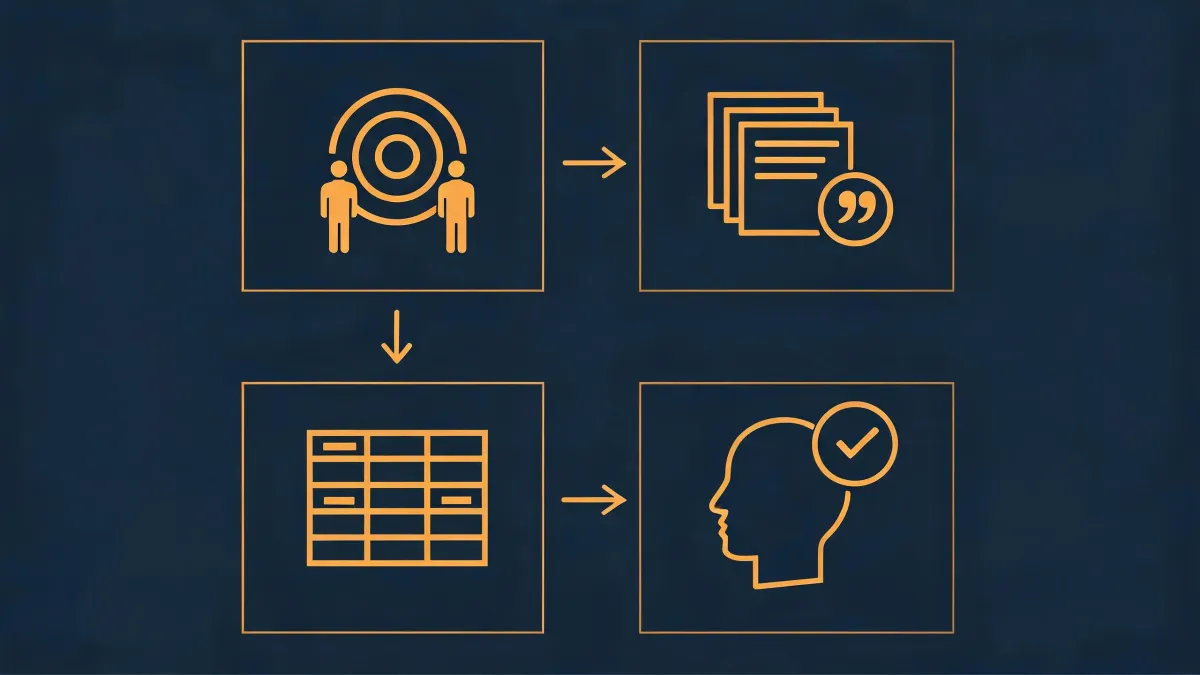
Test on your own messy list. Not the vendor's sample. Take 500 contacts from your worst-quality source—the CSV you've been avoiding, the old event list, the inbound form fills with personal domains. Run both verification and enrichment. Measure bounce on a small send sample before you scale.
Ask about failure modes explicitly. What does the tool do with catch-alls? Role-based addresses? Domain-only matches? A vendor that has a clear answer for each is probably a vendor worth trusting on the rest.
Look at the workflow, not the feature list. LinkedIn Sales Navigator integration doesn't mean much if it produces the same bounce-prone list as your manual export. The question is whether the integration adds quality on top of convenience—freshness, validation, or matching against multiple sources—or just automates the transfer.
Be honest about where you want humans. Fully automated AI SDR stacks work for some lists. For most B2B outbound lists I've seen, they don't, and the fix isn't a better classifier. It's a different workflow shape. Tools that assume a human touchpoint somewhere in the pipeline—Okki Go's review step being one example, though it's not the only design pattern that works—tend to hold up better once real data hits them.
One more thing, and this is where I'll admit my own bias: I've started trusting vendors more when they tell me what they don't do well. A specialist tool that says "we're not the right fit for enterprise-grade compliance workflows" or "if you need verified mobile numbers, look elsewhere" earns more credibility with me than a pitch that claims to cover everything. Generalists sell. Specialists ship. That said, this is my own heuristic after a few years of vendor management—it's not a universal rule.
The short version
Email verification accuracy isn't a product attribute. It's a product-times-your-data attribute. Evaluate it on your data. Test bounce rates on real sends before scaling. Keep the human review step wherever your trust level demands it.
And the next time a vendor shows you a 98% accuracy number in a demo, ask them to run it on the list you're actually going to send to. That conversation tells you more than any feature comparison will.
Pricing, benchmarks, and platform-specific thresholds referenced above are based on our internal testing and public documentation as of early 2026. Verify current rates and platform policies directly with vendors and providers before making purchasing decisions.