-
The comparison framework: what I'm comparing and why
-
Dimension 1: Data collection—manual exports vs. no-code scraping
-
Dimension 2: Buyer intent data—guessing vs. signals in motion
-
Dimension 3: Accuracy and cleanup—who checks the work?
-
Dimension 4: Compliance and boundaries—the part nobody wants to talk about
-
Dimension 5: Cost and time—small teams deserve good tools
-
Which workflow should you choose?
I'm not a data scientist, and I'm not a LinkedIn compliance expert. I'm a RevOps person who has handled B2B prospecting and lead generation for the past six years. In that time, I've personally made (and documented) 14 significant mistakes, totaling roughly $38,000 in wasted budget—including one spreadsheet that was so badly deduped that we emailed the same CFO three times in a week.
When I first started managing prospecting workflows in 2019, I assumed that if I had LinkedIn Sales Navigator and a decent CRM, the pipeline would take care of itself. It didn't. The real challenge wasn't finding people. It was turning messy search results into trustworthy pipeline data. That's what pushed me to compare two ways of working: old-school manual prospecting and a newer agent-native workflow using tools like Phantombuster.
This article is that comparison. I'll share the dimensions that matter most, where I was wrong, and what I'd do differently.
The comparison framework: what I'm comparing and why
Manual prospecting means you sit in front of LinkedIn Sales Navigator, run your filters, export a CSV, and then clean it by hand. Then you enrich it manually too—checking Instagram profiles, looking for personal websites, guessing whether this person actually influences the buying decision.
An agent-native workflow means you define a target account or persona once, and then a no-code agent handles the repetitive parts. For example, a Phantombuster automation can run a LinkedIn search export, pull Instagram profile information, and send enriched rows into your CRM through Make, Zapier, or n8n. Your team only steps in when a human judgment call is required.
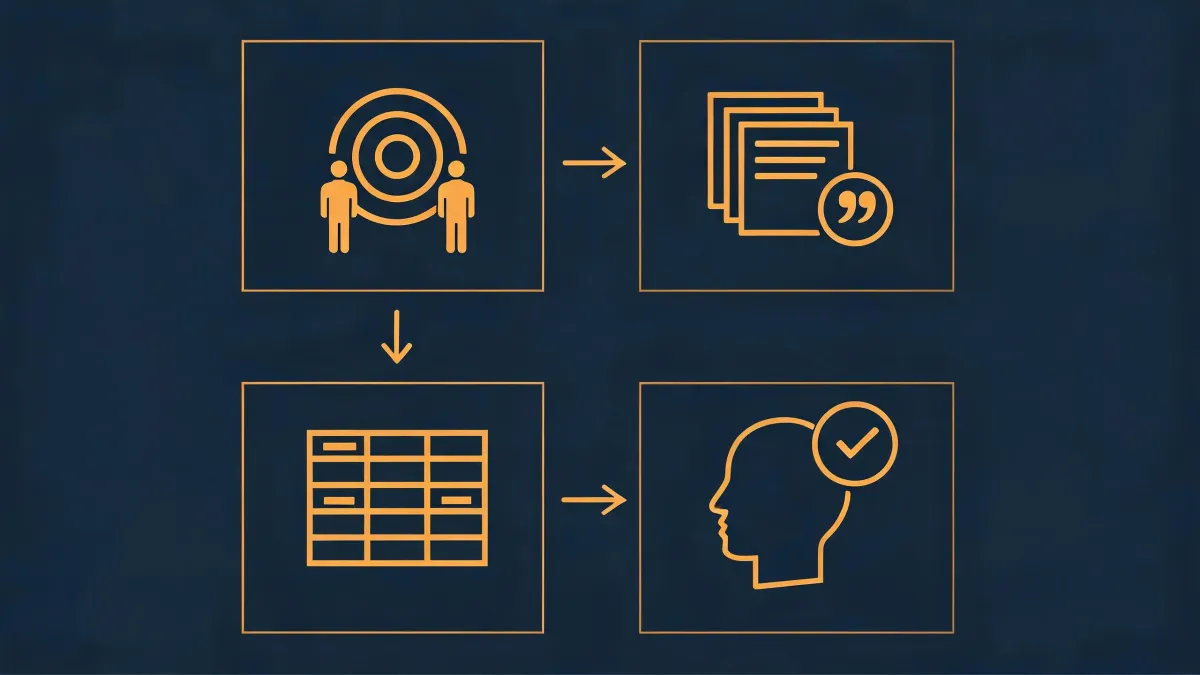
To make the comparison useful, I used five dimensions: data collection, buyer intent integration, accuracy and cleanup, compliance, and cost/time.
Dimension 1: Data collection—manual exports vs. no-code scraping
This is where I made my first big mistake. I used to think manual exports were safer. 'If I run the search myself,' I told myself, 'I'll catch the errors.'
Then I spent a week manually copying 400 LinkedIn search results into a CRM and somehow transposed the seniority filter. Every 'VP Operations' row was actually 'VP of Operations Analytics' because I copied from the wrong column. That error cost $3,200 in wasted SDR time and pushed the campaign back by a week.
Manual prospecting has a hidden bottleneck: your attention. You skip rows, misread companies, and mix up columns when you're tired. It starts fine and degrades fast.
According to Phantombuster's public feature documentation, the LinkedIn search export takes a Sales Navigator search URL and returns a CSV with structured fields—name, headline, company, profile URL. The consistency is the point. You still have to validate the output, but you can validate the whole batch instead of checking each row.
The same lesson applies to social profiles. Phantombuster's Instagram profile scraper features let me pull bios, follower counts, links, and post metrics into one structured file. I used to do that by hand for every prospect who came through our sales engineer's Instagram activity. That was absurd. It took maybe ten minutes per profile. The scraper does the whole list while I'm in a meeting.
Counterintuitive lesson: automated export is not automatically better. It's faster, but it still needs validation. The real benefit is that you catch configuration errors in minutes, not hours.
Dimension 2: Buyer intent data—guessing vs. signals in motion
Let's talk about 'B2B buyer intent data' because that phrase gets thrown around a lot. A lot of people think it means some algorithm tells you exactly who is ready to buy. That's not how it works.
Buyer intent data is a set of behavioral clues. Someone visits your pricing page. A company downloads your competitor comparison. A startup posts a job req for a RevOps analyst. These are signals. They tell you who is becoming relevant, not necessarily who is ready to sign.
In a manual workflow, you might notice a signal in your CRM and then spend 20 minutes searching for the right contact at that account. In an agent-native workflow, the signal can trigger the search automatically:
- Your marketing automation tool scores an account as high intent because the CIO downloaded your security whitepaper.
- A webhook fires to Phantombuster.
- Phantombuster runs a LinkedIn search export for 'RevOps Manager' at that account.
- The rows land in your CRM via Zapier, and the SDR gets a task with context attached.
That's not magic. It's just connecting a signal to an action.
The mistake I made? I once bought a 'buyer intent' list from a data vendor and pasted it into Salesforce. It had 2,000 rows with zero context. We spent two weeks calling people who had no idea why we were calling. The data wasn't wrong; the workflow didn't fit the data. An agent-native workflow doesn't make intent data useful by itself—it makes intent data usable by attaching it to a real next step.
So, how does B2B buyer intent data fit into an agent-native prospecting workflow? It fits as the trigger, not the output. The agent's job is to turn an intent signal into a targeted contact list. Without intent, an agent is just a faster way to build a database you don't actually need.
Dimension 3: Accuracy and cleanup—who checks the work?
I need to be honest here. I used to think that moving from manual to automated scraping would mean the end of data cleanup. Ha.
Manual gives you control over every row. Automated gives you control over the configuration. Configuration errors are just as dangerous as manual errors—they're just faster and more consistent.
Here's a concrete example. I set up a Phantombuster Instagram profile scraper to enrich a list of startup founders. I selected the mapping wrong, and the scraper put 'followers' into the 'biography' field. So the CRM said a founder's bio was '12,847.' It looked ridiculous. We caught it only because one SDR noticed before sending an email. (Not that we always catch things on time.)
The same goes for LinkedIn search export. The export is only as good as the search URL you start with. If the filters are off, you'll get a perfect list of the wrong people.
My conclusion after all those mistakes: automation changes where you spend your quality control, not whether you need it. It handles the boring part. You still need a pre-check list.
Dimension 4: Compliance and boundaries—the part nobody wants to talk about
I'm not a compliance attorney, so I won't pretend to give legal advice. This is where I have mixed feelings about LinkedIn automation as a category.
On one hand, tools like Phantombuster let you extract publicly available search results from LinkedIn. On the other, how you use those results matters. LinkedIn's User Agreement places limits on automated access, and those limits are not always clear. The safest approach I know is to use Phantombuster's LinkedIn search export for lead generation research, not for automated engagement—no auto-connect, no auto-messaging.
Three rules I now follow:
- Read the User Agreement before you build a workflow, not after.
- Use agents for extraction, not for reaching out to people.
- Ignore any vendor that says 'guaranteed compliance.' That guarantee doesn't exist.
In the manual vs. agent-native comparison, this is the dimension where the 'manual is safer' myth is strongest. But manual prospecting has compliance risks too—especially when someone exports a large list and shares it without thinking about data protection rules.
Dimension 5: Cost and time—small teams deserve good tools
This is the part where my 'small customer' bias shows. A lot of comparison articles assume you have a six-figure sales ops budget. I don't, and neither did the teams I worked with.
Manual prospecting looks free until you count the hours. In one of my earlier roles, I calculated that our SDRs spent about 30% of their week on data entry and list cleaning. That's like paying a $60,000 salary for a $15,000 data-entry job.
Agent-native workflows with Phantombuster have a subscription cost, plus integration fees. It's not the cheapest platform on the market. I won't tell you it is. But for a small team, the math often works out when you count the hours you get back.
There's also the 'today's small customer may be tomorrow's big customer' principle. When I was starting out, the vendors who treated my $200 orders seriously are the ones I still use for $20,000 orders. The same goes for tools. If a platform only works for enterprises, it's not the right fit for an SMB sales team testing its first automated workflow. Small doesn't mean unimportant—it means potential.
Which workflow should you choose?
After all this, you might expect me to announce a clean winner: 'Agent-native wins.' But that's not how I make decisions anymore.
Use manual prospecting if:
- You only need a one-time list of fewer than 50 highly curated accounts.
- You don't have integration tools or the budget to connect them.
- You're still defining your ICP and need the hands-on feel.
Use an agent-native workflow with Phantombuster if:
- You need repeatable exports at scale—weekly LinkedIn search exports or Instagram profile scraping for hundreds of leads.
- You already have a CRM and want it to update itself without begging an SDR to do data entry.
- You're ready to invest in a validation checklist instead of row-by-row manual work.
My final piece of advice is a little counterintuitive: start with the checklist, not the tool. The mistake I repeated most was adopting a new tool before defining what 'done' looks like. If you know your target fields, your compliance boundaries, and your scoring rules, Phantombuster's sales prospecting features will make your life easier. If you don't, it will just make your mistakes faster.