When I first started reviewing outbound campaigns for quality, I assumed more personalization was strictly better. More research, more unique first lines, more AI in the loop. Two quarters and roughly 60 killed campaigns later, I realized that was wrong — at least for a chunk of the teams I was reviewing.
Some context on who's writing this. I handle quality and brand compliance for outbound at a B2B SaaS company. Every sequence, list, and sending domain goes past me before it ships — call it 400 campaigns a year. In 2024 I rejected about 22% of first drafts, mostly for deliverability reasons, occasionally for brand voice. Sometimes both in the same email, which is always a fun Slack thread.
So when someone asks me how AI personalization fits into an agent-native prospecting workflow, I can't give a single answer. I've watched a three-person team burn a few thousand dollars a quarter on tooling they didn't need. I've also watched a 40-rep org roughly double its meeting rate with basically the same stack. The difference was context, not the software.
Here's how I break it down.
The three variables that actually decide this
Forget headcount for a second. What matters in practice is these three:
- Deliverability headroom. How many sending domains you have, how old they are, and how much volume they're already carrying.
- Data quality. Whether your enrichment data is verified or just "probably right." There's a big gap between those two words.
- Human review capacity. How many people can look at output before it ships. If the answer is "nobody, the agent just sends," that changes everything downstream.
If you're low on all three, your answer looks nothing like the answer for a team that's high on all three. Most content about "AI SDRs" or sales engagement platform features glosses over this and just describes the high-end version. That's a red flag for me, because it means the writer has only worked with one kind of team.
Scenario A: Founder-led sales or a 1–3 person team
My honest advice here runs against what most vendors will tell you: don't automate the personalization yet. Not deeply, anyway.
At your volume — say 300 to 500 sends a week — the bottleneck isn't outreach capacity. It's message-market fit. You don't know yet what makes someone reply. If you hand that question to an agent, you're automating a hypothesis you haven't validated. All you'll get is faster garbage.
When I first took over quality review, I assumed the teams with the most tooling were the most sophisticated. Nope. The founder-led teams with the best reply rates were the ones doing 30 to 50 accounts a week entirely by hand — looking at the person's LinkedIn, reading their company's last earnings call, writing a two-line opener. That's not scalable, and it doesn't need to be. It's a research process that produces the data you'll later feed to a machine.
There's also a hard technical reason. Most small teams send from one domain. A single domain pushing 500+ cold emails a day is a no-brainer way to torch your deliverability — and once that domain's reputation is gone, it does not come back fast.
Since February 2024, Google requires bulk senders (5,000+ messages a day to Gmail accounts) to authenticate with SPF, DKIM and DMARC, keep spam complaint rates under 0.3% (they recommend staying under 0.1%), and support one-click unsubscribe per RFC 8058. Yahoo introduced comparable requirements. Source: Google Postmaster guidelines at postmaster.google.com. Verify current thresholds — they do get updated.
You might be under 5,000/day and technically outside those rules. Doesn't matter. The thresholds are a decent proxy for "what a mailbox provider considers normal," and if you're dramatically past them on a young domain, your emails are going to the spam folder whether or not there's a rule about it.
Bottom line for Scenario A: fix your data and your domain reputation first, do the personalization by hand, and revisit tooling when you're at 5+ reps.
Scenario B: 5–30 person SDR org with decent CRM hygiene
This is where AI personalization starts paying for itself. You've got enough volume that manual research doesn't scale, and you've got enough data that an agent has something real to work with.
The setup I've seen work, over and over, is tiered. Not every account gets the same treatment:
- Tier 1 (top 50–100 accounts, quarterly). Deep research. Human + AI. Bespoke messaging, sometimes multi-threaded.
- Tier 2 (a few hundred accounts). Segment-level personalization driven by intent signals — job postings, funding events, tech stack changes, competitor mentions.
- Tier 3 (everything else). Template with a few well-chosen variables and clean data. Move on.
The counterintuitive part: most teams get this backwards. They try to personalize everything equally and end up with 4,000 emails that all feel kind of the same. The tiering is the actual work. The AI just executes it faster.
This is where the agent-native piece matters. A waterfall enrichment approach — stacking multiple data providers and taking the first verified hit — tends to produce meaningfully cleaner inputs than any single source. And an intent signal layered on top tells the agent why this account, now. That combination is what makes personalization feel like it was written by a human who did homework rather than a model that filled in a first-name slot.
On the okki-go side specifically: what I'd look at during okki go configuration isn't the prompt library, it's the guardrails. What's the source of truth for each data field? What happens when enrichment returns a conflict? What's the suppression logic? Who reviews before send? Configure those first. The copy quality is downstream of all of it.
Scenario C: Agency or high-volume multi-client operation
At 100k+ sends a month across multiple client domains, personalization has to change shape. You cannot write a bespoke email for every contact — the math doesn't work and, honestly, the marginal lift doesn't either.
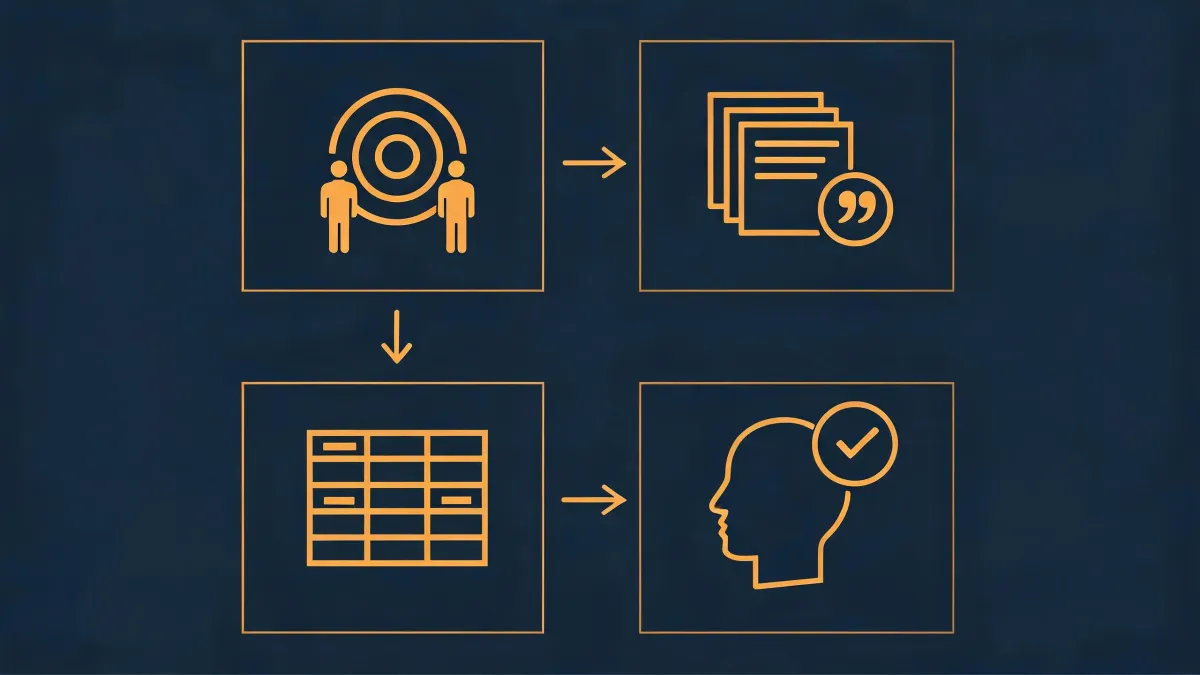
What works here is segment-level personalization with a human-in-the-loop QA layer. The agent pulls intent signals, enriches, drafts from a client-approved template family, and queues output for review. A human approves, edits, or rejects. Then the agent sends, logs, and feeds the outcome back into the next cohort.
I'd flag two things about this setup.
First, the human-in-the-loop step is not a limitation you should try to engineer away. I've seen agencies try to remove it to increase throughput. Every one of them eventually shipped something embarrassing to a client's prospect list — the kind of thing that costs the account. There's a version of "AI sales rep" that means fully autonomous sending. I'd argue that version is a deal-breaker for any client whose brand you're holding.
Second, this is where cheap data becomes expensive. I won't quote exact per-verification prices because they change quarterly and I don't want to be wrong about it — don't hold me to any number I'd throw out. But the arithmetic people miss is this: if your enrichment source is 15% stale and you're sending 100k emails, that's a lot of bounces, and bounces are a spam-complaint generator. A domain that gets flagged costs you weeks of warming and lost pipeline. The $0.001 you saved per contact is the least of it.
In my experience running quality audits across roughly 200 campaigns a year, the campaigns that got pulled for deliverability issues were almost never the ones with the best prompts. They were the ones with the cheapest data pipeline. That's not a coincidence.
How to figure out which scenario you're actually in
Most teams think they're in B and are actually in A. Here's the diagnostic I use:
- How many verified, engaged contacts do you have in your ICP right now? Not total list size. Verified and previously engaged. If it's under a few hundred, you're Scenario A regardless of headcount.
- What's your bounce rate over the last 30 days? If it's above 3%, you have a data problem before you have a personalization problem. Go fix that first.
- How many sending domains, and how many are 6+ months old with a clean history? If the answer is "one," treat yourself as Scenario A for volume purposes.
- Who reads the output before it sends? If it's nobody, and you're over 10k sends a month, you're not in C — you're in a scenario I don't have good advice for.
- Can you name the last three intent signals that produced a meeting? If you can't, you don't have an intent data problem. You have a tracking problem. Different fix.
Roughly speaking, if you answer honestly and land in A, don't buy the enterprise stack yet. If you land in B, tier your list before you touch a single prompt. If you land in C, invest in the review layer — it's the part nobody wants to build because it doesn't scale, which is exactly why it's the part that protects the account.
The question "how does AI personalization fit into an agent-native prospecting workflow" gets sold as a feature comparison. It isn't. It's a question about what your team can actually absorb right now. Answer that first, and the tooling decision gets a lot easier.